Your agent forgets
every session.
llmmemory gives it a memory. Facts are saved as plain Markdown files and handed back at the right moment: an index when a session starts, and the memories that match each message you send. No model, no server, no account.
Claude Code · Codex · Gemini CLI · Cursor · Antigravity · No API key · MIT
What your agent sees
Real hook output, trimmed for width
llmmemory: 3 saved memories. Each line is a name and a summary.
This project:
- deploys-go-through-ship-sh: Deploys go through scripts/ship.sh,
  never straight to main. [deploy]
- sqlite-wal-mode: The database is SQLite in WAL mode.
All projects:
- short-answers: Prefers short answers without preamble.
you › how do I deploy this change?

<memory name="deploys-go-through-ship-sh" scope="project">
Deploys go through scripts/ship.sh, never straight to main.
It runs the checks first and squash-merges the PR.
</memory>
See it in action
Real terminal recordings
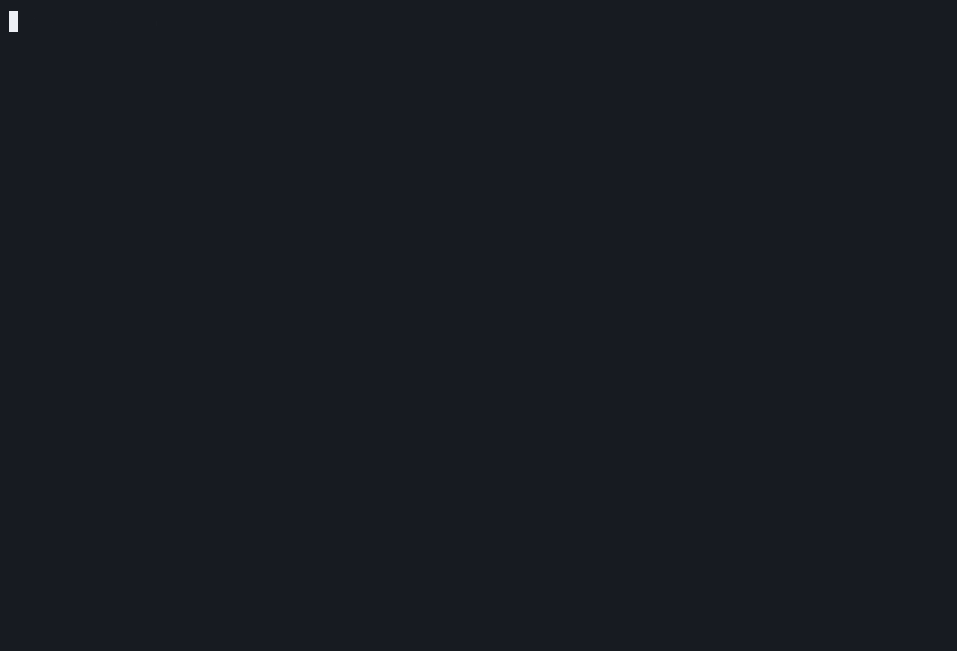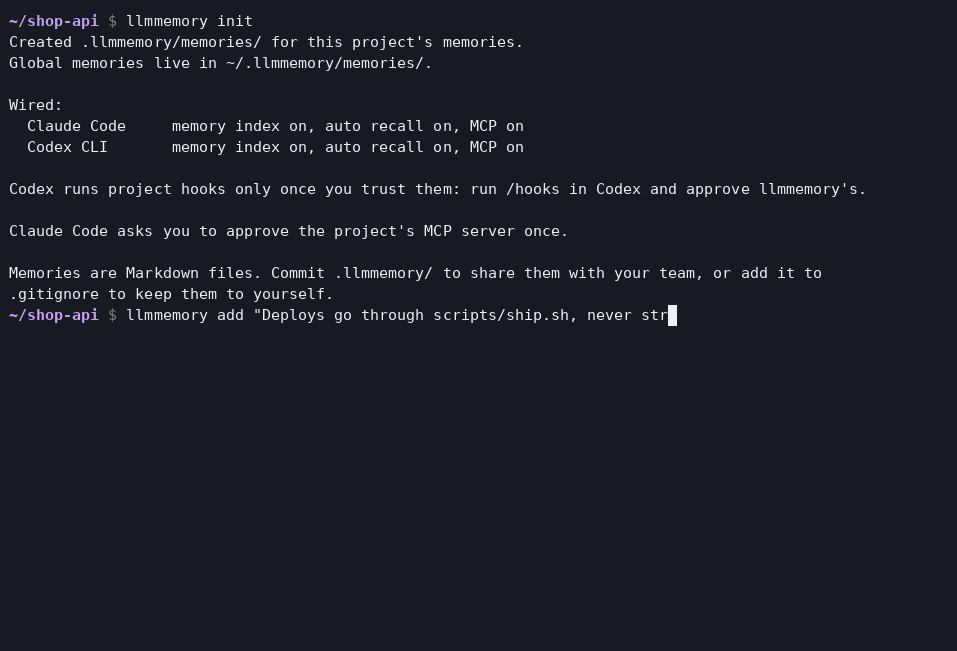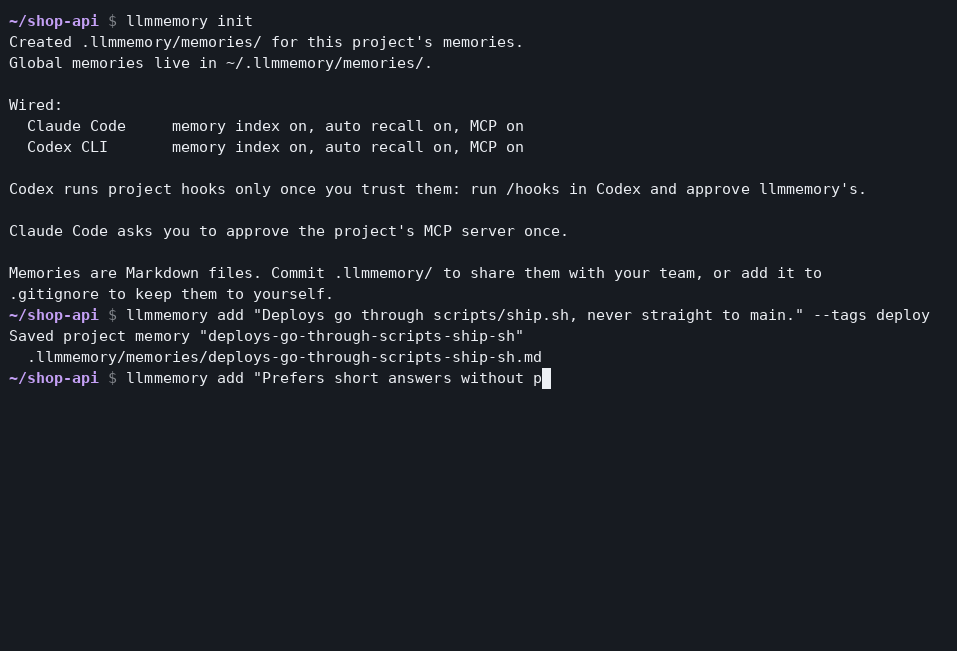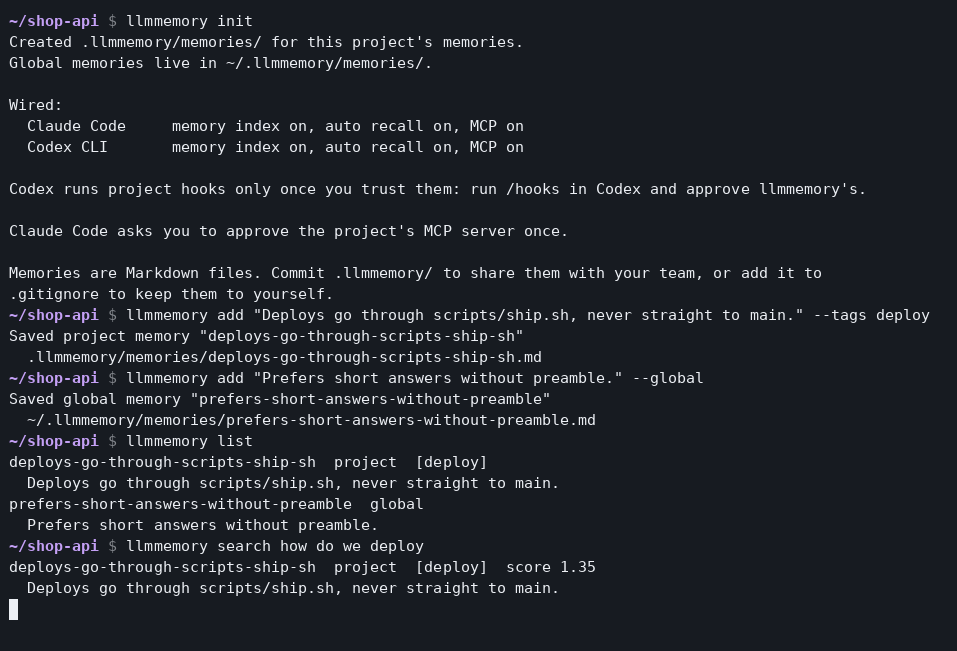
llmmemory initWire your agents, save a few facts
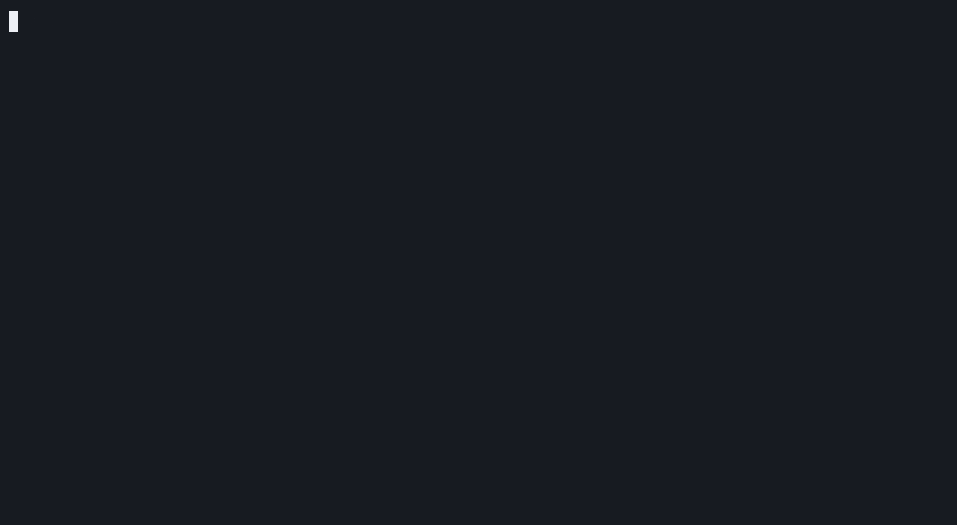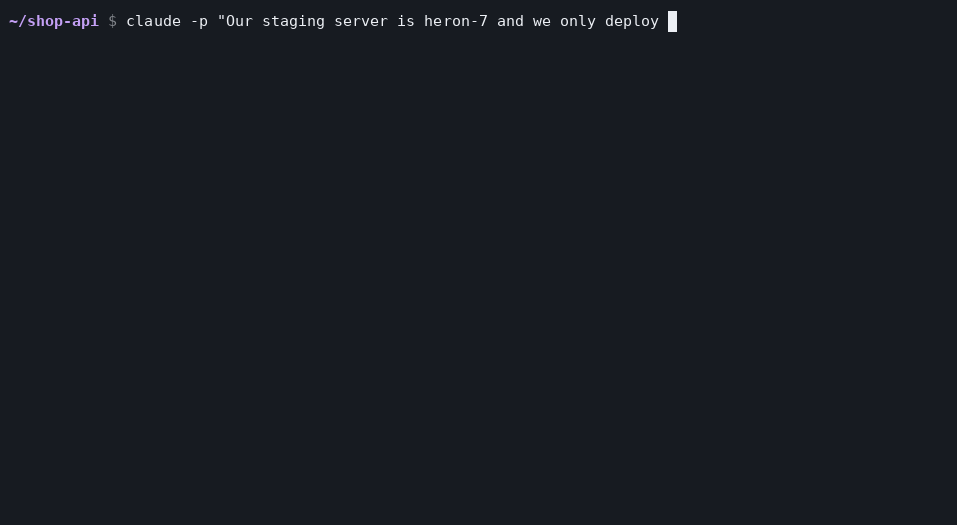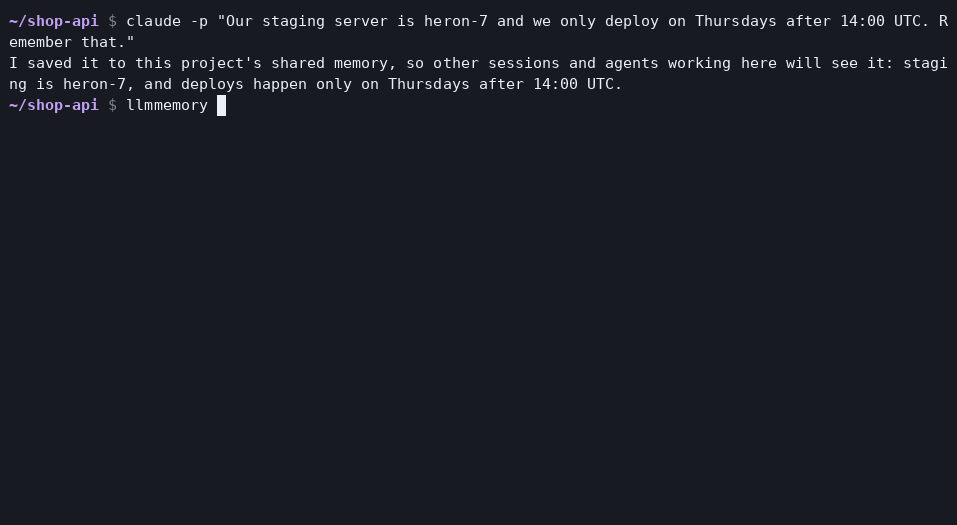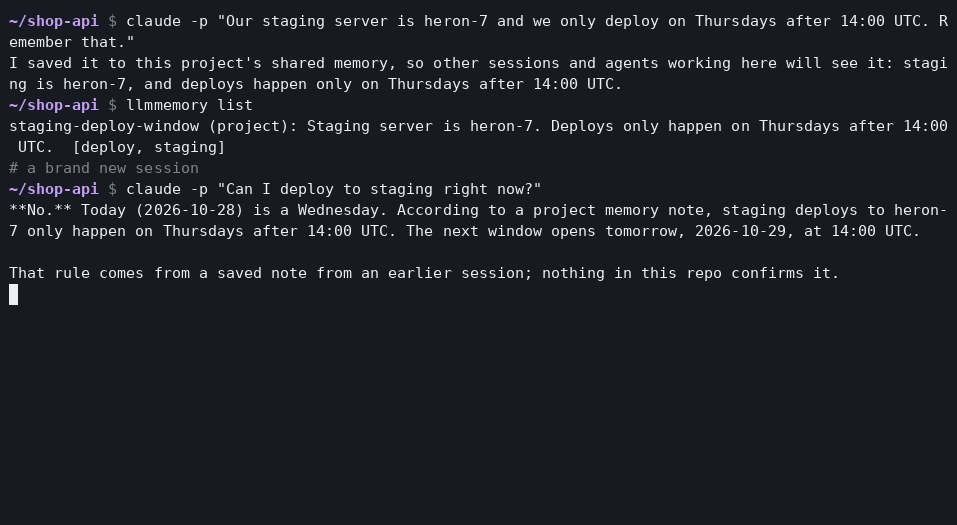
the recallOne Claude Code session saves a fact, the next one uses it
Remembered at the right moment
Not one big file loaded every time. Small memories, each pulled in when the conversation needs it.
An index of what it knows
Every memory's name and one-line summary, project first, then the ones that follow you everywhere. Plus how to save new ones, so the agent keeps the memory growing on its own.
The memories that match
In Claude Code, Codex CLI and Gemini CLI, your message is matched against every memory. Up to three that fit are added in full, each only once per session. An unrelated message adds nothing.
Tools the agent can call
An MCP server with remember, recall, read_memory, forget and list_memories. Registered for every supported agent, and usable from any MCP client.
Memories are files you own
One Markdown file per memory. Read it, fix it, delete it by hand. No database to inspect, no format to decode.
Project memories live in .llmmemory/memories/. Commit the folder and your whole team's agents share what each one learned. Facts about you go in ~/.llmmemory/ and follow you to every project.
---
name: deploys-go-through-ship-sh
description: Deploys go through scripts/ship.sh,
  never straight to main.
tags: [deploy]
created: 2026-10-28T04:11:07.449Z
updated: 2026-10-28T04:11:07.449Z
---

Deploys go through scripts/ship.sh, never
straight to main. It runs the checks first
and squash-merges the PR.
How to use it
Install and wire it up
One command per project. init creates the memory folder and wires Claude Code plus every agent the project already uses, merging with the hooks you have. doctor then runs each hook for real, so a broken install never looks like an empty memory.
npm install -g llmmemory
cd /your/project
llmmemory init
llmmemory doctor
Let the agent save what it learns
Every session is told what is worth keeping: preferences, decisions and their reasons, non-obvious facts. And what is not: anything the code or git history already records.
llmmemory add "Deploys go through scripts/ship.sh." --tags deploy
Teach it about you once
Global memories apply in every project, so a preference stated once is never asked again.
llmmemory add "Prefers short answers without preamble." --global
Keep it honest
Search what it knows, update a memory that changed, forget one that turned out wrong. Updating by name keeps one memory per fact instead of a pile of near-duplicates.
llmmemory search deploy
llmmemory add "Deploys now run in GitHub Actions." --name deploys-go-through-ship-sh
llmmemory forget sqlite-wal-mode
What is worth remembering
The things you explain to a new teammate in their first week, and then never have to explain again.
Your preferences
How you like answers written, which tools you reach for, what you never want it to do again.
Decisions and why
Why the queue is Postgres and not Redis. The reason is what the next session needs, and the code never says it.
Hard-won fixes
The build flag that took an afternoon to find. Next time it is one recall away.
Project lore
The staging server's name, the deploy day, the module nobody should touch without asking.
Nine commands
Every one takes --json.
llmmemory initCreate .llmmemory/ and wire the hooks and MCP serverllmmemory add "<fact>"Save a memory; --global for every project, --name to update onellmmemory listEvery memory, project then globalllmmemory search <words>Find memories by keyword, best match firstllmmemory show <name>Print one memory in fullllmmemory forget <name>Delete a memory that turned out wrongllmmemory doctorRun every wired hook and the MCP server to prove they answerllmmemory statusWhere memories live and what each agent getsllmmemory cleanUnwire every agent; memories are keptWhat it does not do
Recall matches words, not meaning. A message about "shipping" will not find a memory that only says "deploy". Tags close most of that gap, and the agent can always search.
Cursor and Antigravity CLI do not show their hooks your message, so they get the index at session start and recall the rest through the MCP server, when the agent decides to call it.
It remembers what gets saved. A memory is only as good as the fact behind it, so the agent is told to check memories against the code before acting on them.
Questions
Doesn't Claude Code already have memory?
Claude Code reads CLAUDE.md files, which you write and maintain. llmmemory is the part the agent writes: small facts saved as they come up, recalled only when a message needs them, instead of one file loaded in full every time.
Does it need an AI model or an API key?
No. Recall is keyword search with BM25-style ranking: rare words count for more, and a match in a memory's name or tags outweighs one in its body. It runs in milliseconds, and nothing leaves your machine.
Where are my memories stored?
As Markdown files in .llmmemory/memories/ for the project and ~/.llmmemory/memories/ for facts that apply everywhere. Read them, edit them, delete them, or commit the project folder to share it with your team.
Will it fill my context window?
No. A session starts with one line per memory, capped in size. A message pulls in at most three memories, each only once per session, and a lone common word is not enough to recall anything.
Which agents does it work with?
Claude Code, Codex CLI, Gemini CLI, Cursor and Antigravity CLI. All five get the memory index when a session starts and the MCP tools. Claude Code, Codex and Gemini CLI also get matching memories added to each message; Cursor and Antigravity do not show their hooks the message, so there the agent looks memories up through MCP.
Can a memory hijack my agent?
Recalled memories are wrapped and labelled as notes from earlier sessions, not instructions from you, and a memory cannot close its own wrapper. Still, anything in .llmmemory/ reaches the agent, so review memory files in pull requests the way you would a CLAUDE.md change.